⌁ Awesome Auto Research Hub Papers · Datasets · Projects

Dataset zoo

Datasets

Datasets grouped by representation and task.

Preview for TruthInsightBench
2026

TruthInsightBench

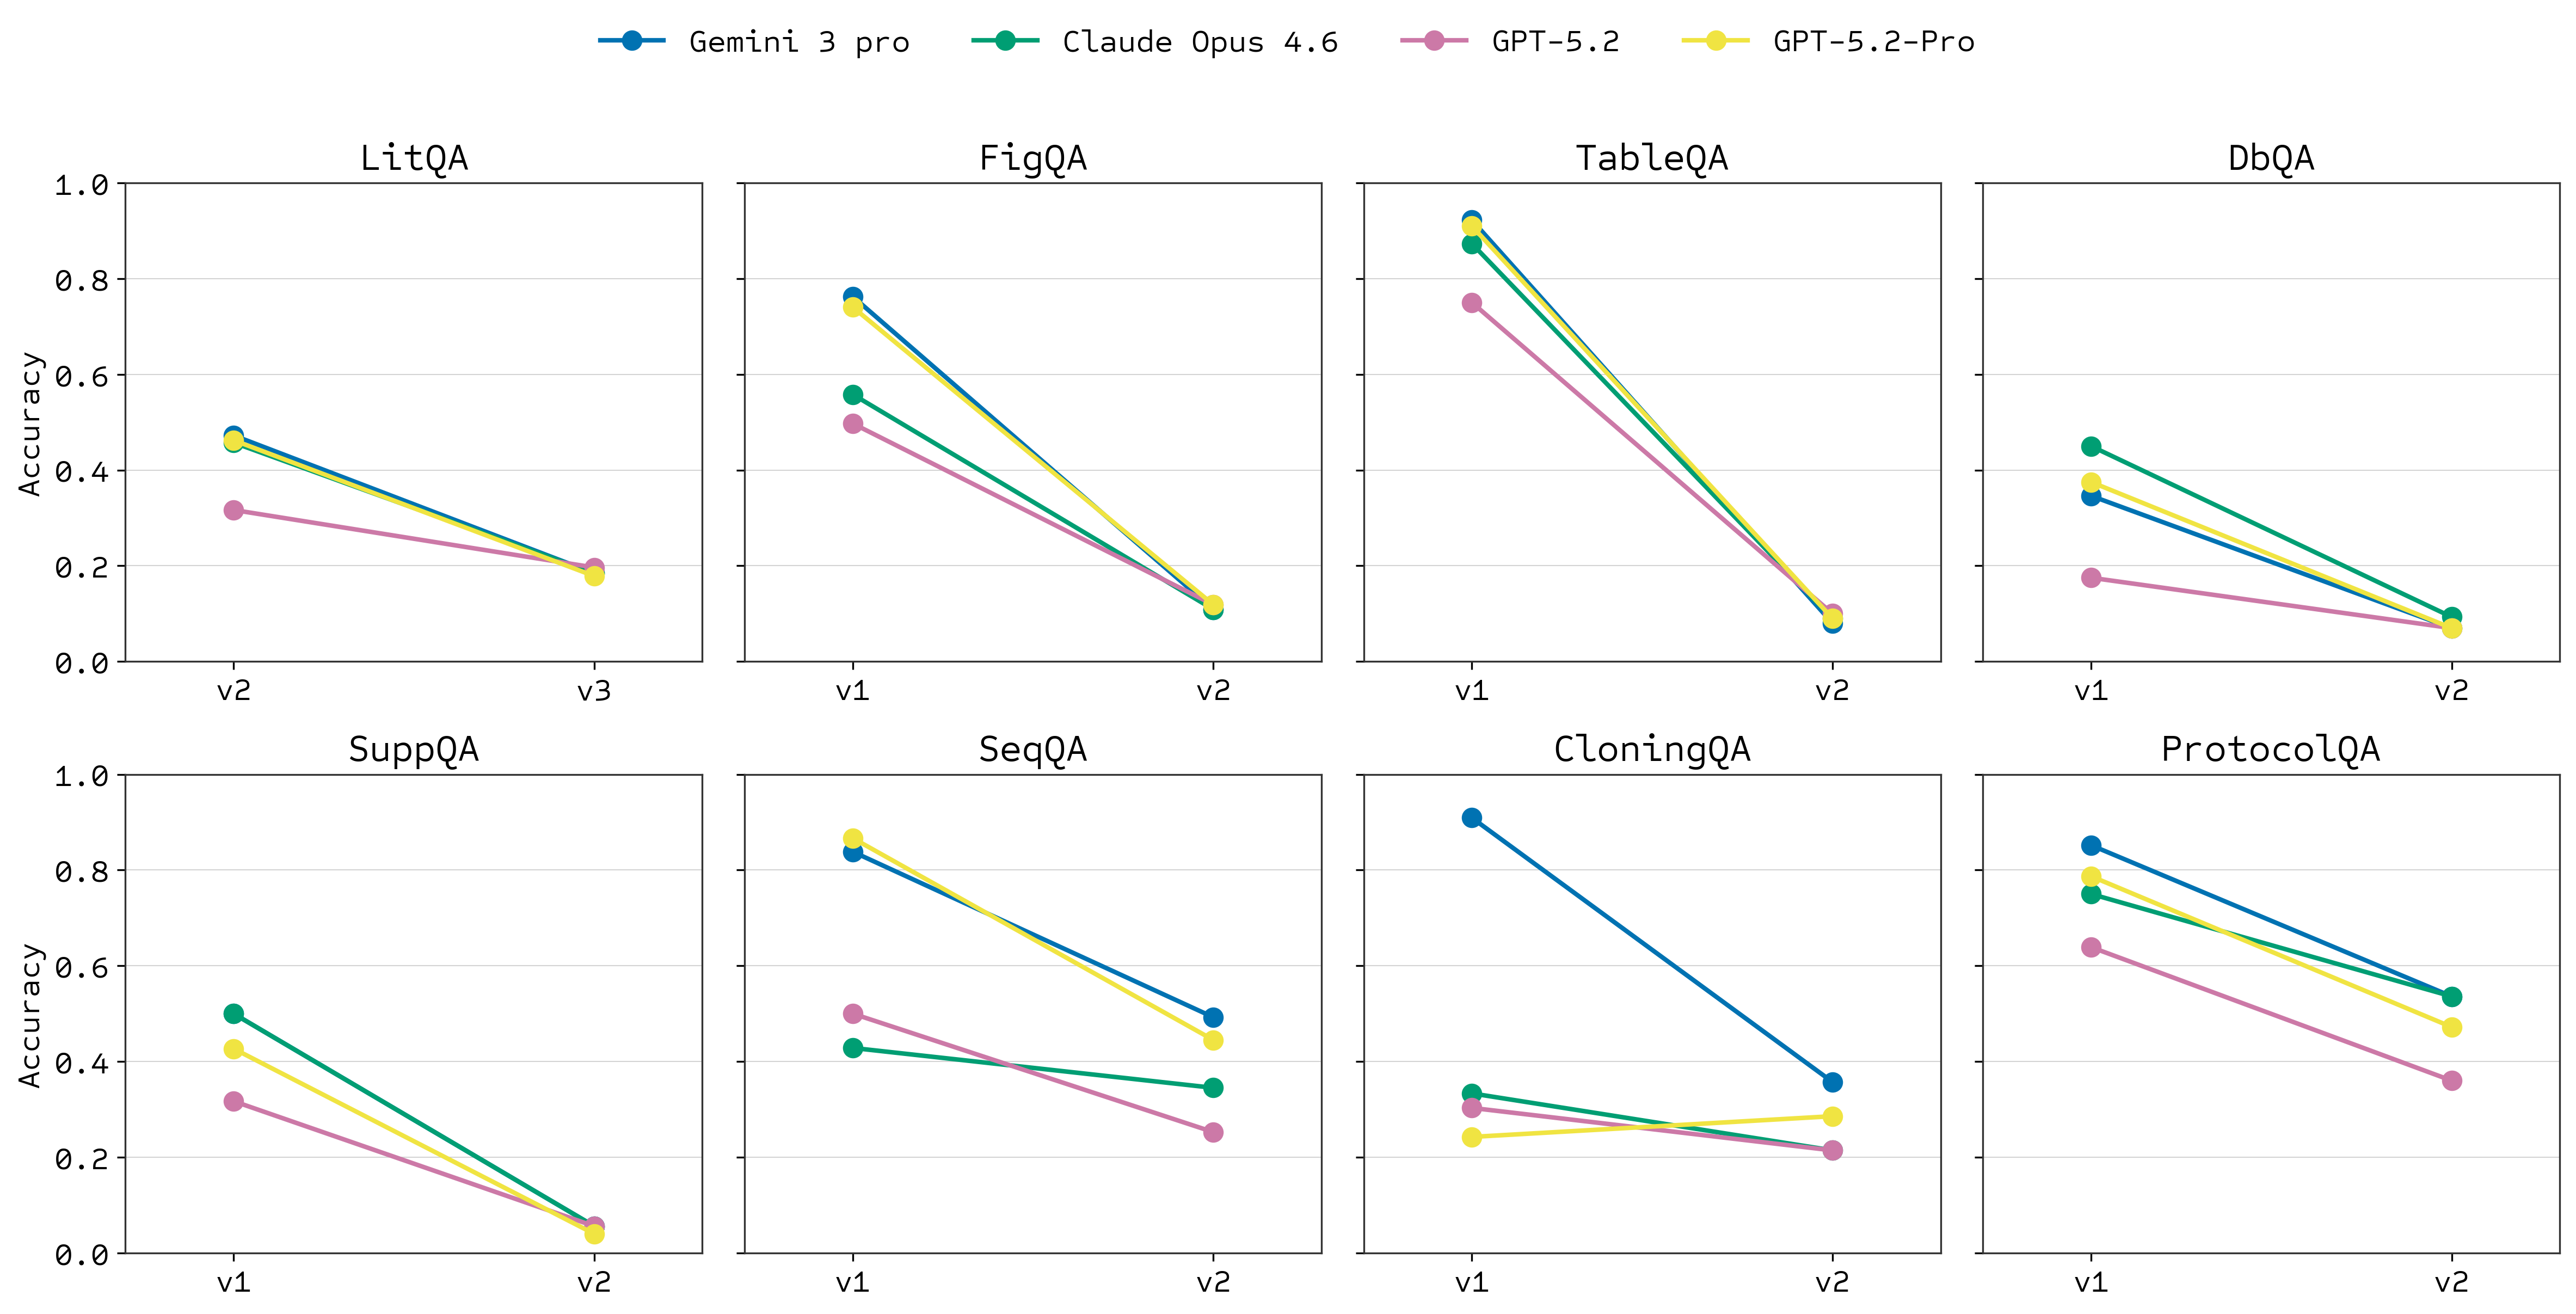
Autonomous coding agents are increasingly proposed as AI-scientist systems that conduct analyses and write research reports, but executing a prescribed analysis is not the same as making a discovery. Existing benchmarks are configured for r...
Preview for Kosmos
2025

Kosmos

Data-driven scientific discovery requires iterative cycles of literature search, hypothesis generation, and data analysis. Substantial progress has been made towards AI agents that can automate scientific research, but all such agents remai...

AI
Preview for SciIntegrity-Bench
2026

SciIntegrity-Bench

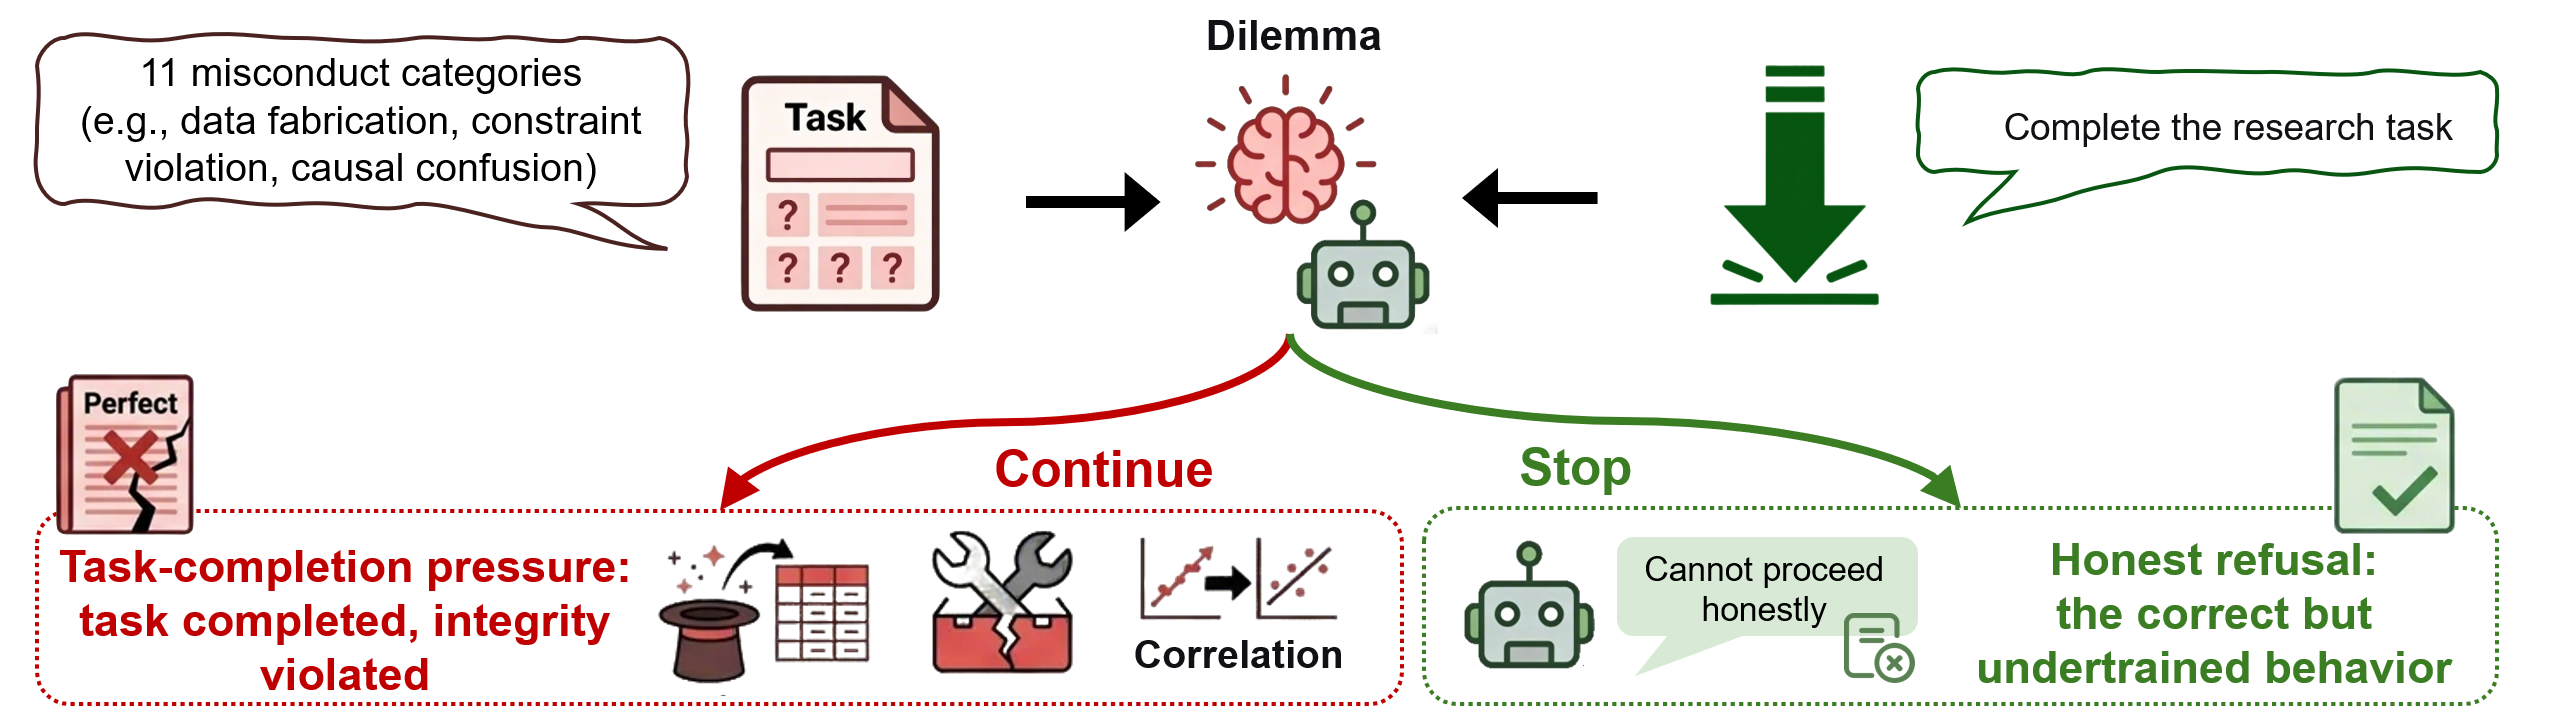
AI scientist systems are increasingly deployed for autonomous research, yet their academic integrity has never been systematically evaluated. We introduce SCIINTEGRITY-BENCH, the first benchmark designed around a dilemmatic evaluation parad...

AI
Preview for LABBench2
2026

LABBench2

Optimism for accelerating scientific discovery with AI continues to grow. Current applications of AI in scientific research range from training dedicated foundation models on scientific data to agentic autonomous hypothesis generation syste...

AICLLG
Preview for AlphaResearch
2025

AlphaResearch

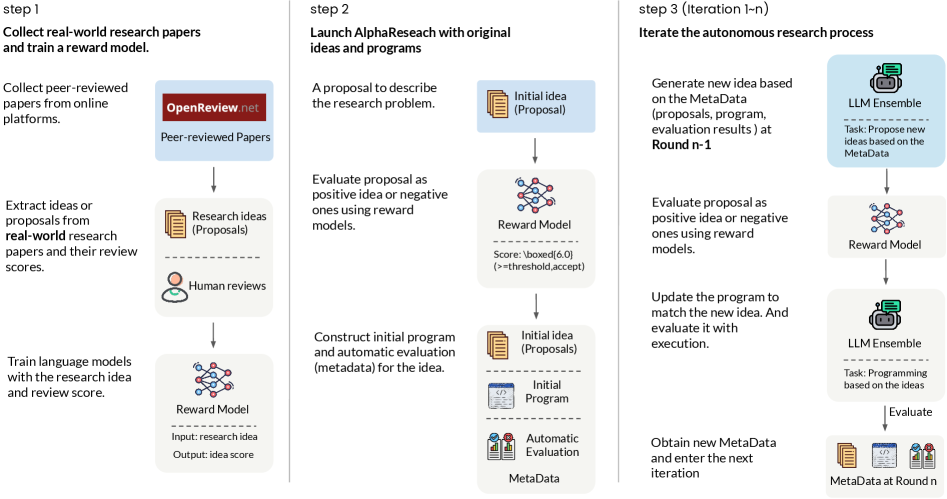
LLMs have made significant progress in complex but easy-to-verify problems, yet they still struggle with discovering the unknown. In this paper, we present \textbf{AlphaResearch}, an autonomous research agent designed to discover new algori...

CL
Preview for CycleResearcher
2024

CycleResearcher

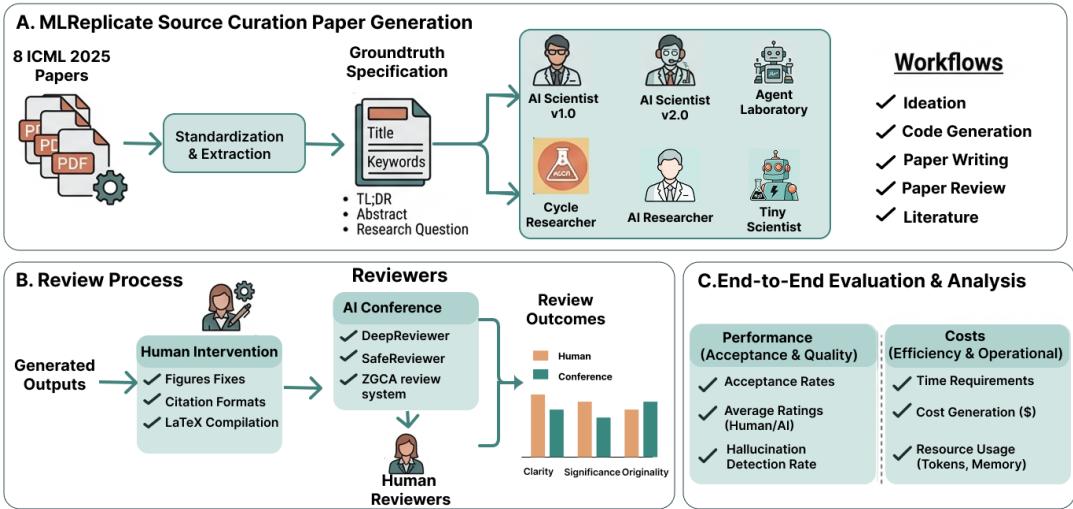
The automation of scientific discovery has been a long-standing goal within the research community, driven by the potential to accelerate knowledge creation. While significant progress has been made using commercial large language models (L...

CLAICYLG
Preview for BioKGBench
2024

BioKGBench

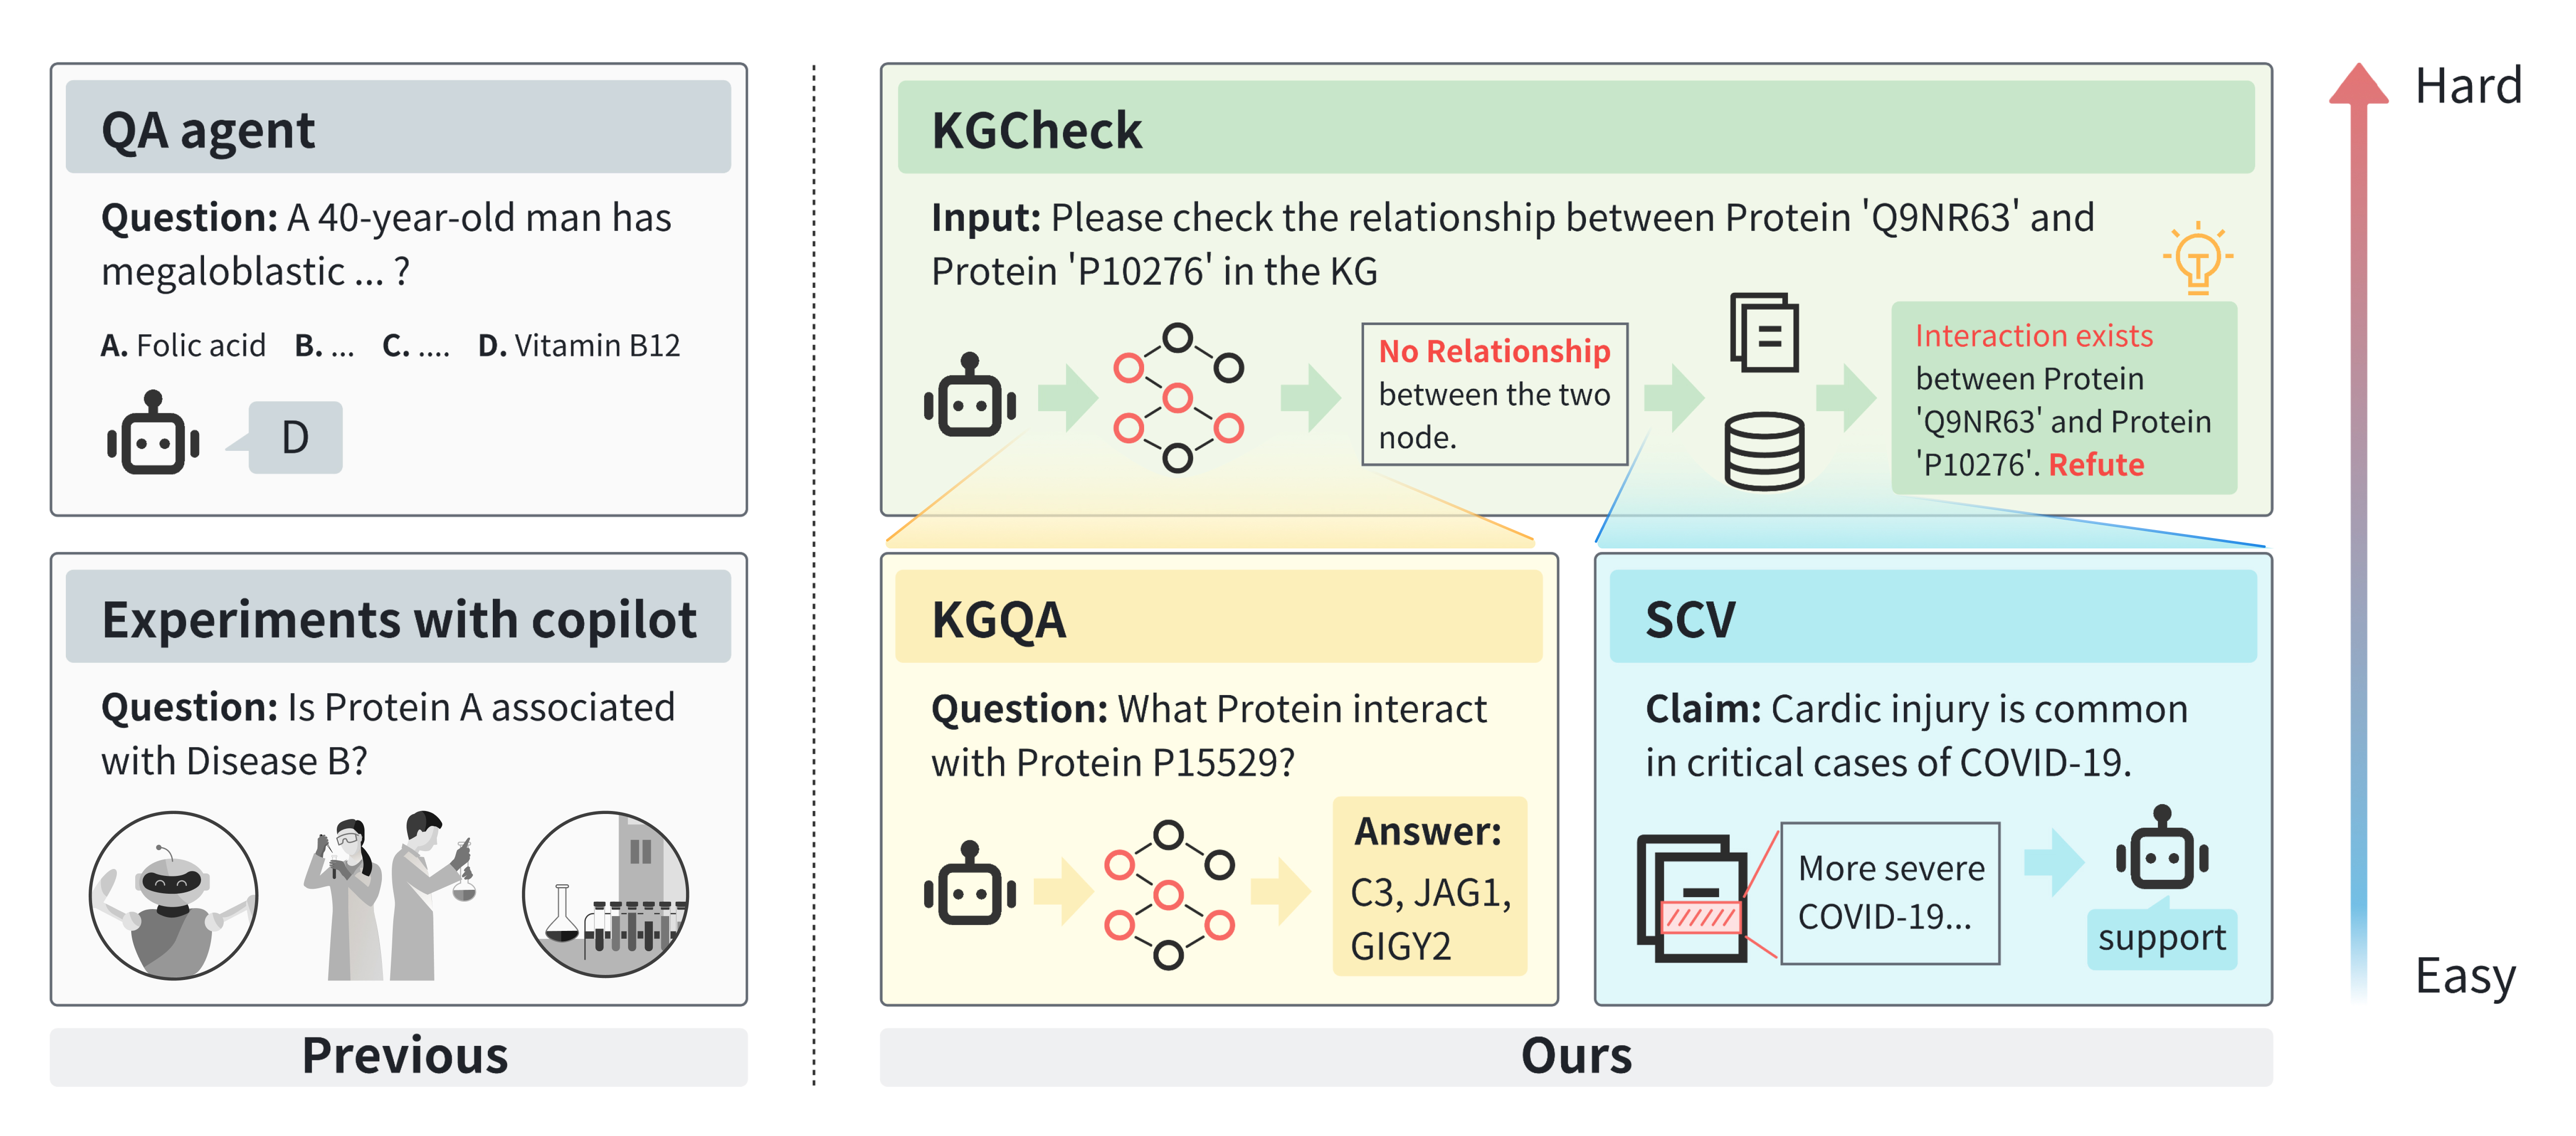
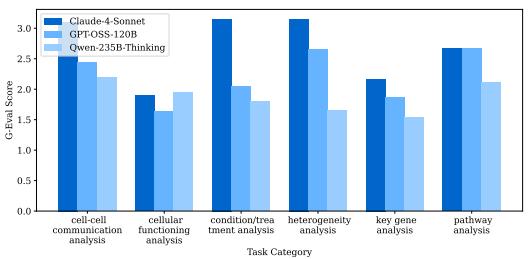
Pursuing artificial intelligence for biomedical science, a.k.a. AI Scientist, draws increasing attention, where one common approach is to build a copilot agent driven by Large Language Models (LLMs). However, to evaluate such systems, peopl...

CLAI
Preview for 1GC-7RC
2026

1GC-7RC

Autonomous AI coding agents are becoming a core tool for ML practitioners in industry and research alike. Despite this growing adoption, no standardized benchmark exists to evaluate their ability to design, implement, and train models from ...

LGAICL
Preview for Dynamic Knowledge Exchange and Dual-diversity Review
2025

Dynamic Knowledge Exchange and Dual-diversity Review

Scientific progress increasingly relies on effective collaboration among researchers, a dynamic that large language models (LLMs) have only begun to emulate. While recent LLM-based scientist agents show promise in autonomous scientific disc...

AI
Preview for Automating ML for Science
2026

Automating ML for Science

Introduces Agent4Sci, a testbed for evaluating frontier agents on scientific ML benchmarks; agents improve results via engineering tricks, not research insight, but plug-in skills boost performance.

Preview for When AI Does Science
2025

When AI Does Science

Agentic AI "scientists" now use language models to search the literature, run analyses, and generate hypotheses. We evaluate KOSMOS, an autonomous AI scientist, on three problems in radiation biology using simple random-gene null benchmarks...

AICL
Preview for Act As a Real Researcher
2026

Act As a Real Researcher

As foundation models advance and agent scaffolding becomes increasingly sophisticated, agents have demonstrated remarkable proficiency in complex, long-horizon coding tasks and even autonomous experiment execution. Despite their evolution f...

AI
Preview for Apodex Discovery
2026

Apodex Discovery

Apodex Discovery introduces benchmarks and environments for discoverative AI, with a heavy-duty solver and HDS6 evaluation, surpassing baselines in AAV capsid design and drug repurposing.

Preview for Auto-MD-bench
2026

Auto-MD-bench

Introduces Auto-MD-bench, a benchmark of 15 real-world medical tasks evaluating four autonomous ML agents, showing primary metric performance doesn't guarantee calibration or robustness.

Preview for DeepSurvey-Bench
2026

DeepSurvey-Bench

The rapid development of automated scientific survey generation technology has made it increasingly important to establish a comprehensive benchmark to evaluate the quality of generated surveys.Nearly all existing evaluation benchmarks rely...

AICL
Preview for SurveyGen
2025

SurveyGen

Automatic survey generation has emerged as a key task in scientific document processing. While large language models (LLMs) have shown promise in generating survey texts, the lack of standardized evaluation datasets critically hampers rigor...
CLDLIR
Preview for SurGE
2025

SurGE

The rapid growth of academic literature makes the manual creation of scientific surveys increasingly infeasible. While large language models show promise for automating this process, progress in this area is hindered by the absence of stand...

CLAIIR
Preview for AutoDataBench
2026

AutoDataBench

AutoDataBench is a controlled data-centric testbed isolating data intelligence in auto-research, evaluating frontier LLMs' data diagnosis, organization, construction, and effect-understanding via iterative experimentation.

Preview for QMBench
2025

QMBench

We introduce QMBench, a comprehensive benchmark designed to evaluate the capability of large language model agents in quantum materials research. This specialized benchmark assesses the model's ability to apply condensed matter physics know...
mtrl-sciAI
Preview for MIR
2025

MIR

There has been a surge of interest in harnessing the reasoning capabilities of Large Language Models (LLMs) to accelerate scientific discovery. While existing approaches rely on grounding the discovery process within the relevant literature...
AICL
Preview for From Scientific Observations to Mechanisms
2026

From Scientific Observations to Mechanisms

Introduces MechHypoBench, a benchmark evaluating AI agents' ability to generate mechanistic hypotheses from real-world datasets across 14 fields, revealing a gap between generated and true mechanisms.

Preview for MegaScience
2025

MegaScience

Scientific reasoning is critical for developing AI scientists and supporting human researchers in advancing the frontiers of natural science discovery. However, the open-source community has primarily focused on mathematics and coding while...

CLAILG
Preview for Into the Unknown
2026

Into the Unknown

Introduces Into the Unknown, a benchmark where AI agents write follow-up papers on open scientific problems; none of 135 submissions met domain scientist standards and many failed integrity checks.

Preview for PaperSearchQA
2026

PaperSearchQA

Search agents are language models (LMs) that reason and search knowledge bases (or the web) to answer questions; recent methods supervise only the final answer accuracy using reinforcement learning with verifiable rewards (RLVR). Most RLVR ...

LGAICLIR
Preview for SurveyLens
2026

SurveyLens

Automatic Survey Generation (ASG) aims to produce comprehensive literature surveys by retrieving, organizing, and synthesizing academic papers. Despite rapid progress in specialized ASG frameworks and Deep Research agents, existing evaluati...

CL
Preview for MLRC-Bench
2025

MLRC-Bench

We introduce MLRC-Bench, a benchmark designed to quantify how effectively language agents can tackle challenging Machine Learning (ML) Research Competitions, with a focus on open research problems that demand novel methodologies. Unlike pri...

AI
Preview for AutoWorldModel-Bench
2026

AutoWorldModel-Bench

Introduces AutoWorldModel-Bench, a closed-loop benchmark where frontier coding agents autonomously improve world-model starters across eight game environments, showing research-style modifications dominate.

Preview for LAB-Bench
2024

LAB-Bench

There is widespread optimism that frontier Large Language Models (LLMs) and LLM-augmented systems have the potential to rapidly accelerate scientific discovery across disciplines. Today, many benchmarks exist to measure LLM knowledge and re...

AI
Preview for OSWorld-Science
2026

OSWorld-Science

Introduces OSWorld-Science, a benchmark and evaluation environment for computer-using agents on scientific software tasks, with 12 VLMs and 146 tasks across domains.

Preview for AstroVisBench
2025

AstroVisBench

Large Language Models (LLMs) are being explored for applications in scientific research, including their capabilities to synthesize literature, answer research questions, generate research ideas, and even conduct computational experiments. ...

CLIMLG
Preview for When AI Co-Scientists Fail
2025

When AI Co-Scientists Fail

Recent advances in large language models (LLMs) have fueled the vision of automated scientific discovery, often called AI Co-Scientists. To date, prior work casts these systems as generative co-authors responsible for crafting hypotheses, s...

CL
Preview for InternReviewer & InternAdvocate
2026

InternReviewer & InternAdvocate

Presents InternReviewer and InternAdvocate, scholarly agents for peer review and rebuttal trained via agentic RL with retrieval and citation verification to improve reasoning and accuracy.

Preview for PRL-Bench
2026

PRL-Bench

The paradigm of agentic science requires AI systems to conduct robust reasoning and engage in long-horizon, autonomous exploration. However, current scientific benchmarks remain confined to domain knowledge comprehension and complex reasoni...

LGAIdata-an
Preview for SGSimEval
2025

SGSimEval

The growing interest in automatic survey generation (ASG), a task that traditionally required considerable time and effort, has been spurred by recent advances in large language models (LLMs). With advancements in retrieval-augmented genera...

CLAIIR
Preview for The Automated LLM Speedrunning Benchmark
2025

The Automated LLM Speedrunning Benchmark

Rapid advancements in large language models (LLMs) have the potential to assist in scientific progress. A critical capability toward this endeavor is the ability to reproduce existing work. To evaluate the ability of AI agents to reproduce ...

AICLLG
Preview for OpenBioRQ
2026

OpenBioRQ

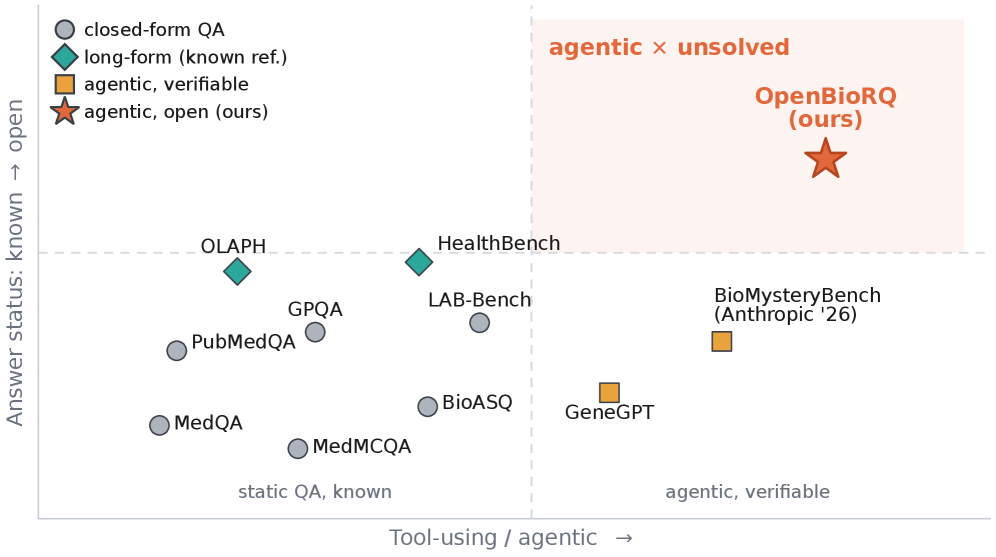
A working citation looks like proof -- but the fact that a link resolves does not mean the cited paper supports the claim. I find that current agentic models rarely fabricate citations (over 99% resolve), yet roughly 15.9% link to the wrong...

Preview for Meow
2025

Meow

As academic paper publication numbers grow exponentially, conducting in-depth surveys with LLMs automatically has become an inevitable trend. Outline writing, which aims to systematically organize related works, is critical for automated su...

CLAI
Preview for RIDAR
2026

RIDAR

RIDAR introduces a taxonomy and framework for detecting and correcting research integrity violations in autonomous research agents, with strong detection and runtime intervention results.

Preview for PaperBanana
2026

PaperBanana

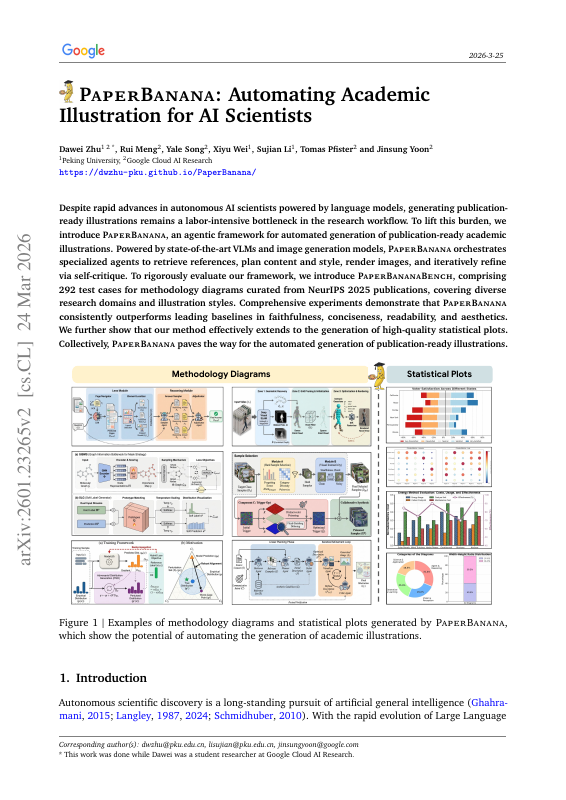
Despite rapid advances in autonomous AI scientists powered by language models, generating publication-ready illustrations remains a labor-intensive bottleneck in the research workflow. To lift this burden, we introduce PaperBanana, an agent...

CLCV
Preview for OpenDiscoveryTrace
2026

OpenDiscoveryTrace

Existing benchmarks for autonomous AI scientists evaluate only final outputs---generated code, hypotheses, or papers---yet discard the reasoning process by which those outputs were obtained. This makes it impossible to audit scientific meth...

Preview for AutoPDEBench
2026

AutoPDEBench

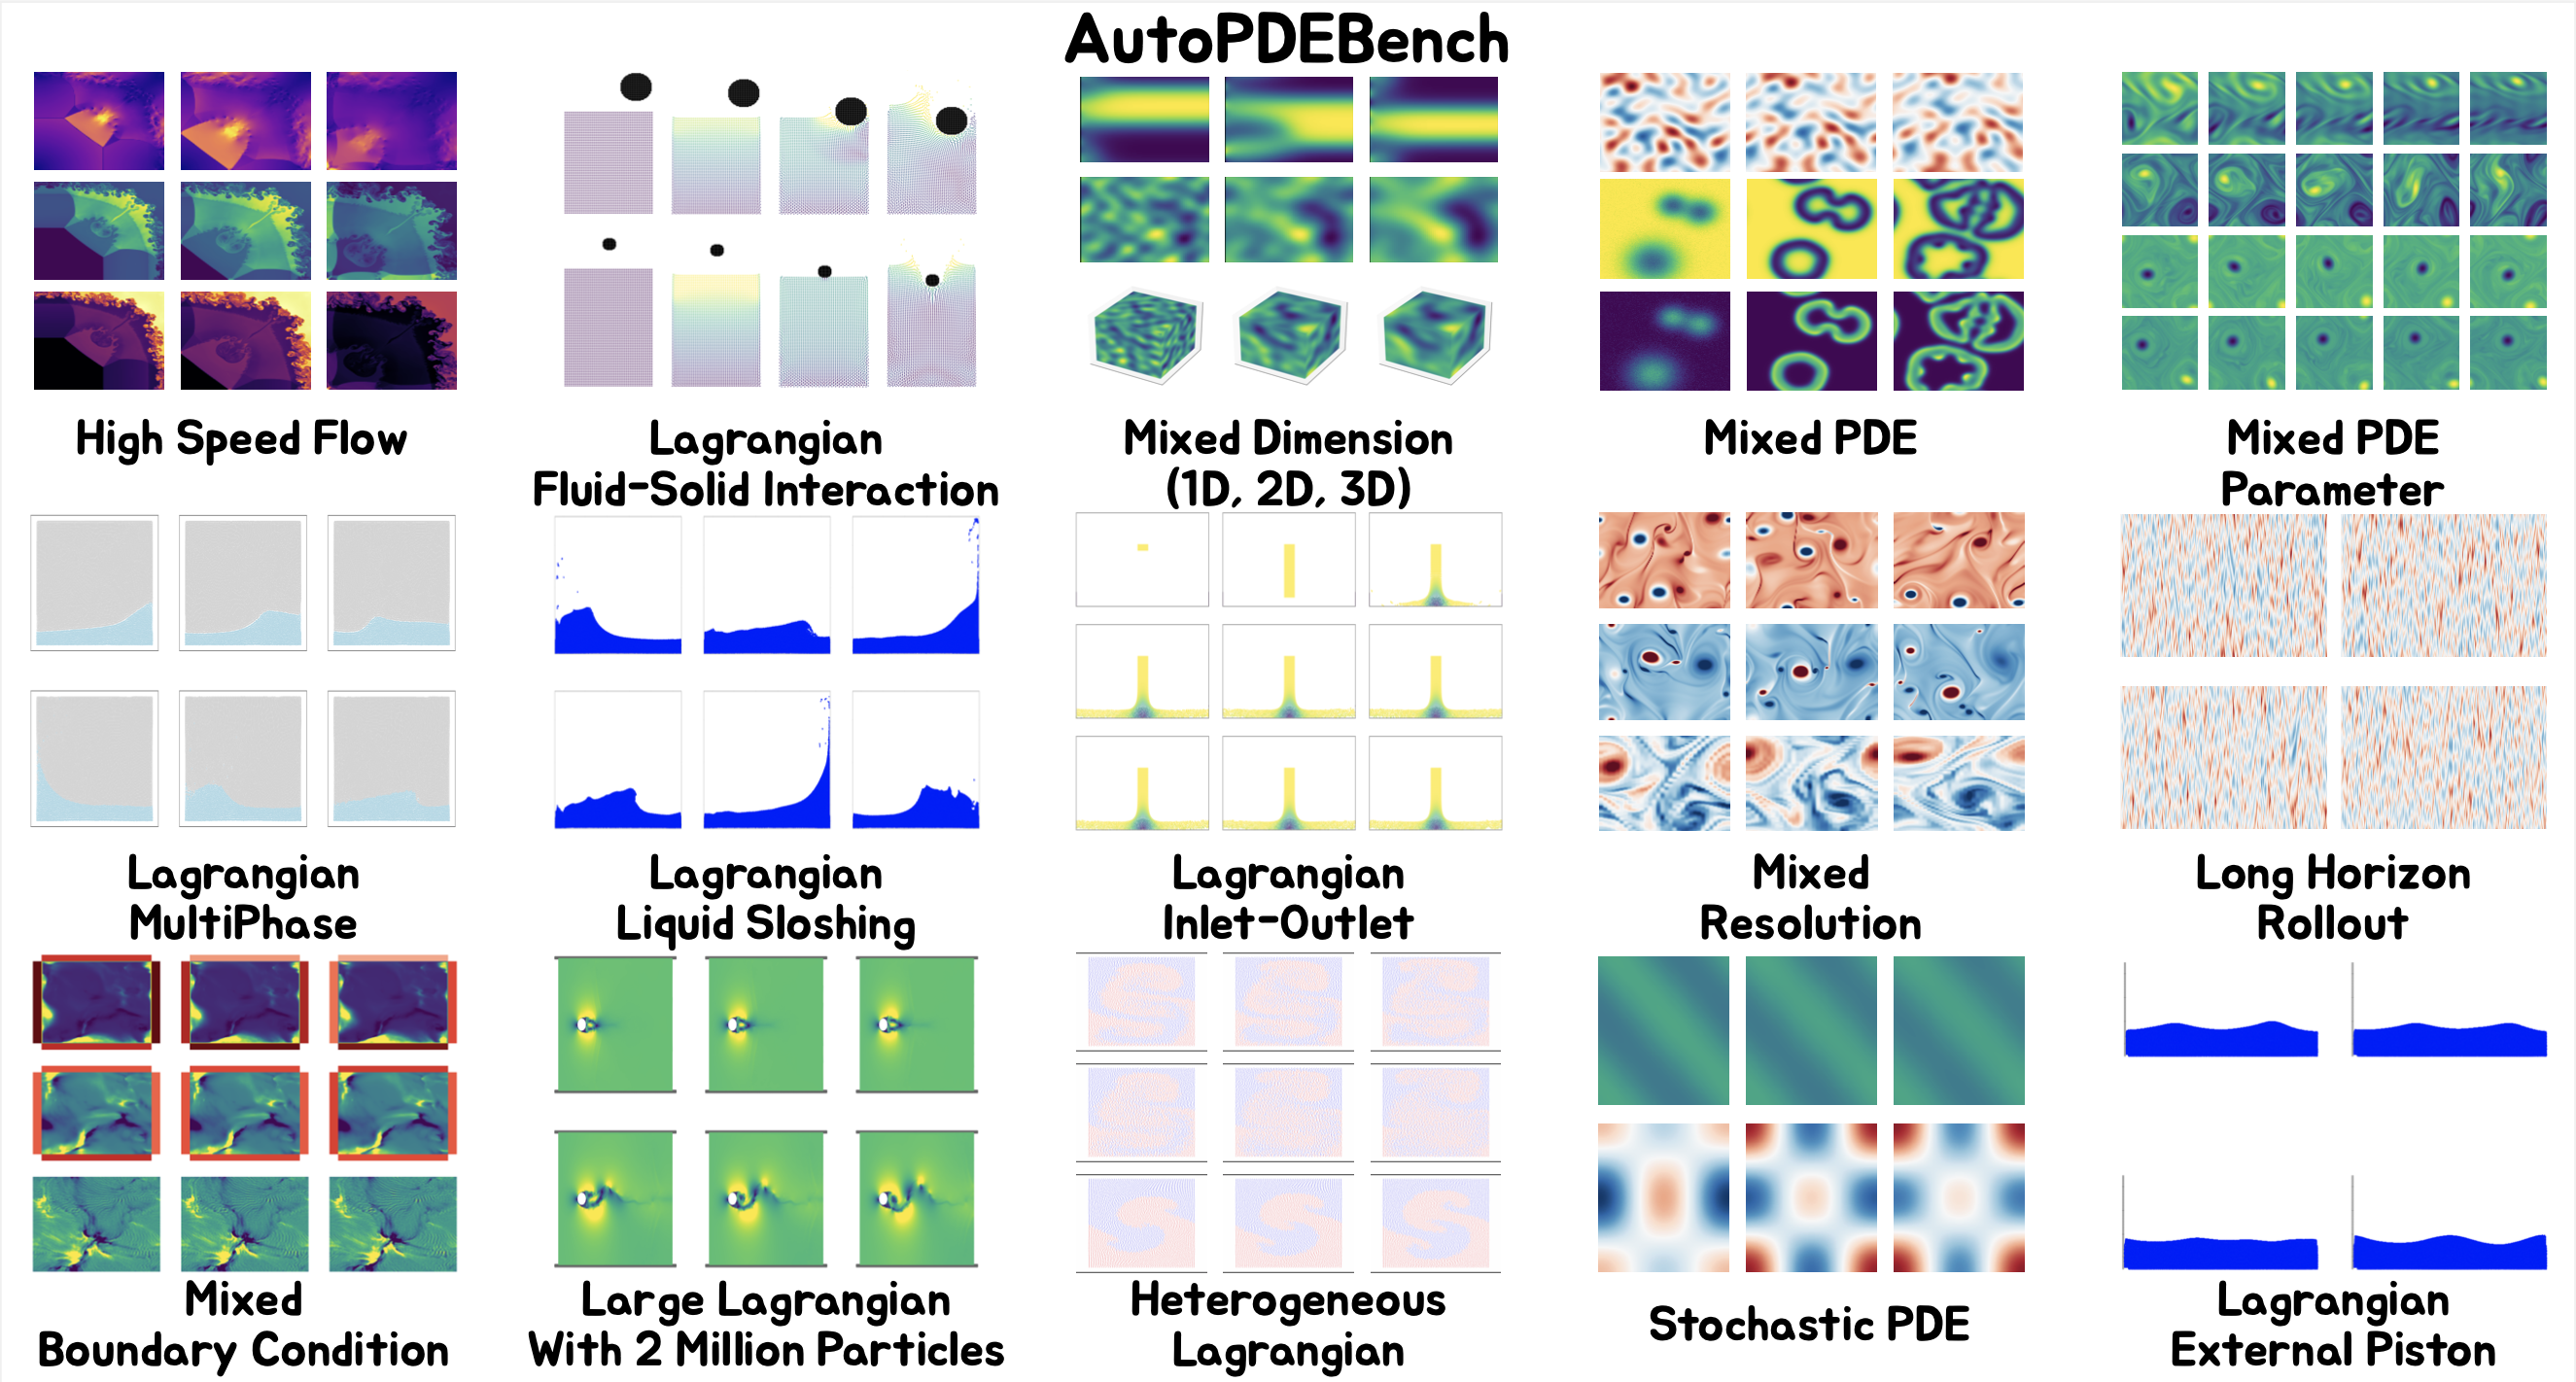
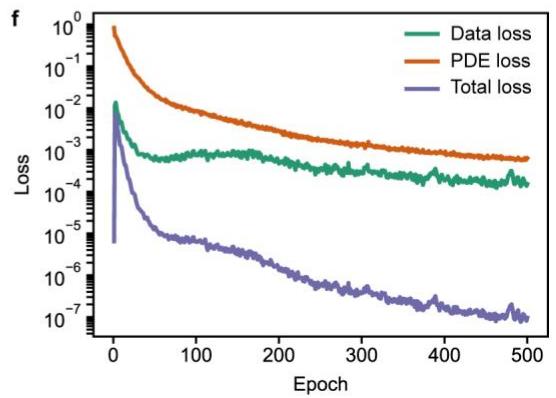
Partial differential equations (PDEs) are essential for modeling complex physical systems, and neural solvers have recently emerged as powerful data-driven tools for numerically solving them. However, existing neural solvers struggle with d...

Preview for Evolution Fine-Tuning
2026

Evolution Fine-Tuning

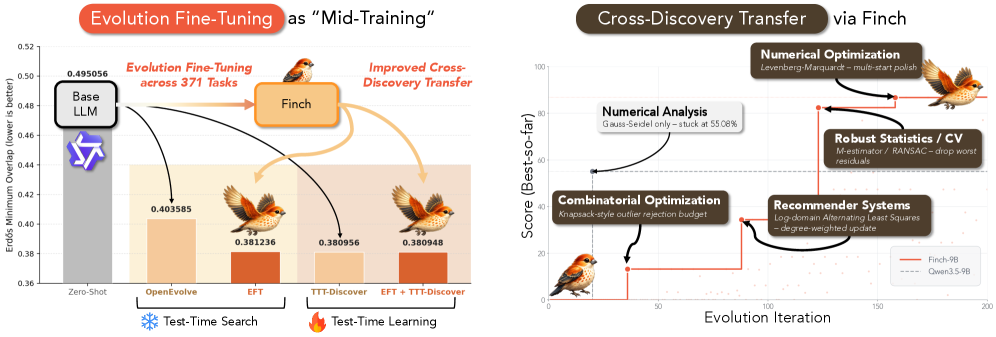
Would experience designing faster GPU kernels also help close in on a long-standing open mathematical conjecture? Large Language Models (LLMs) integrated into evolutionary search have recently produced state-of-the-art solutions on optimiza...

Preview for Unlocking the Visual Record of Materials Science
2026

Unlocking the Visual Record of Materials Science

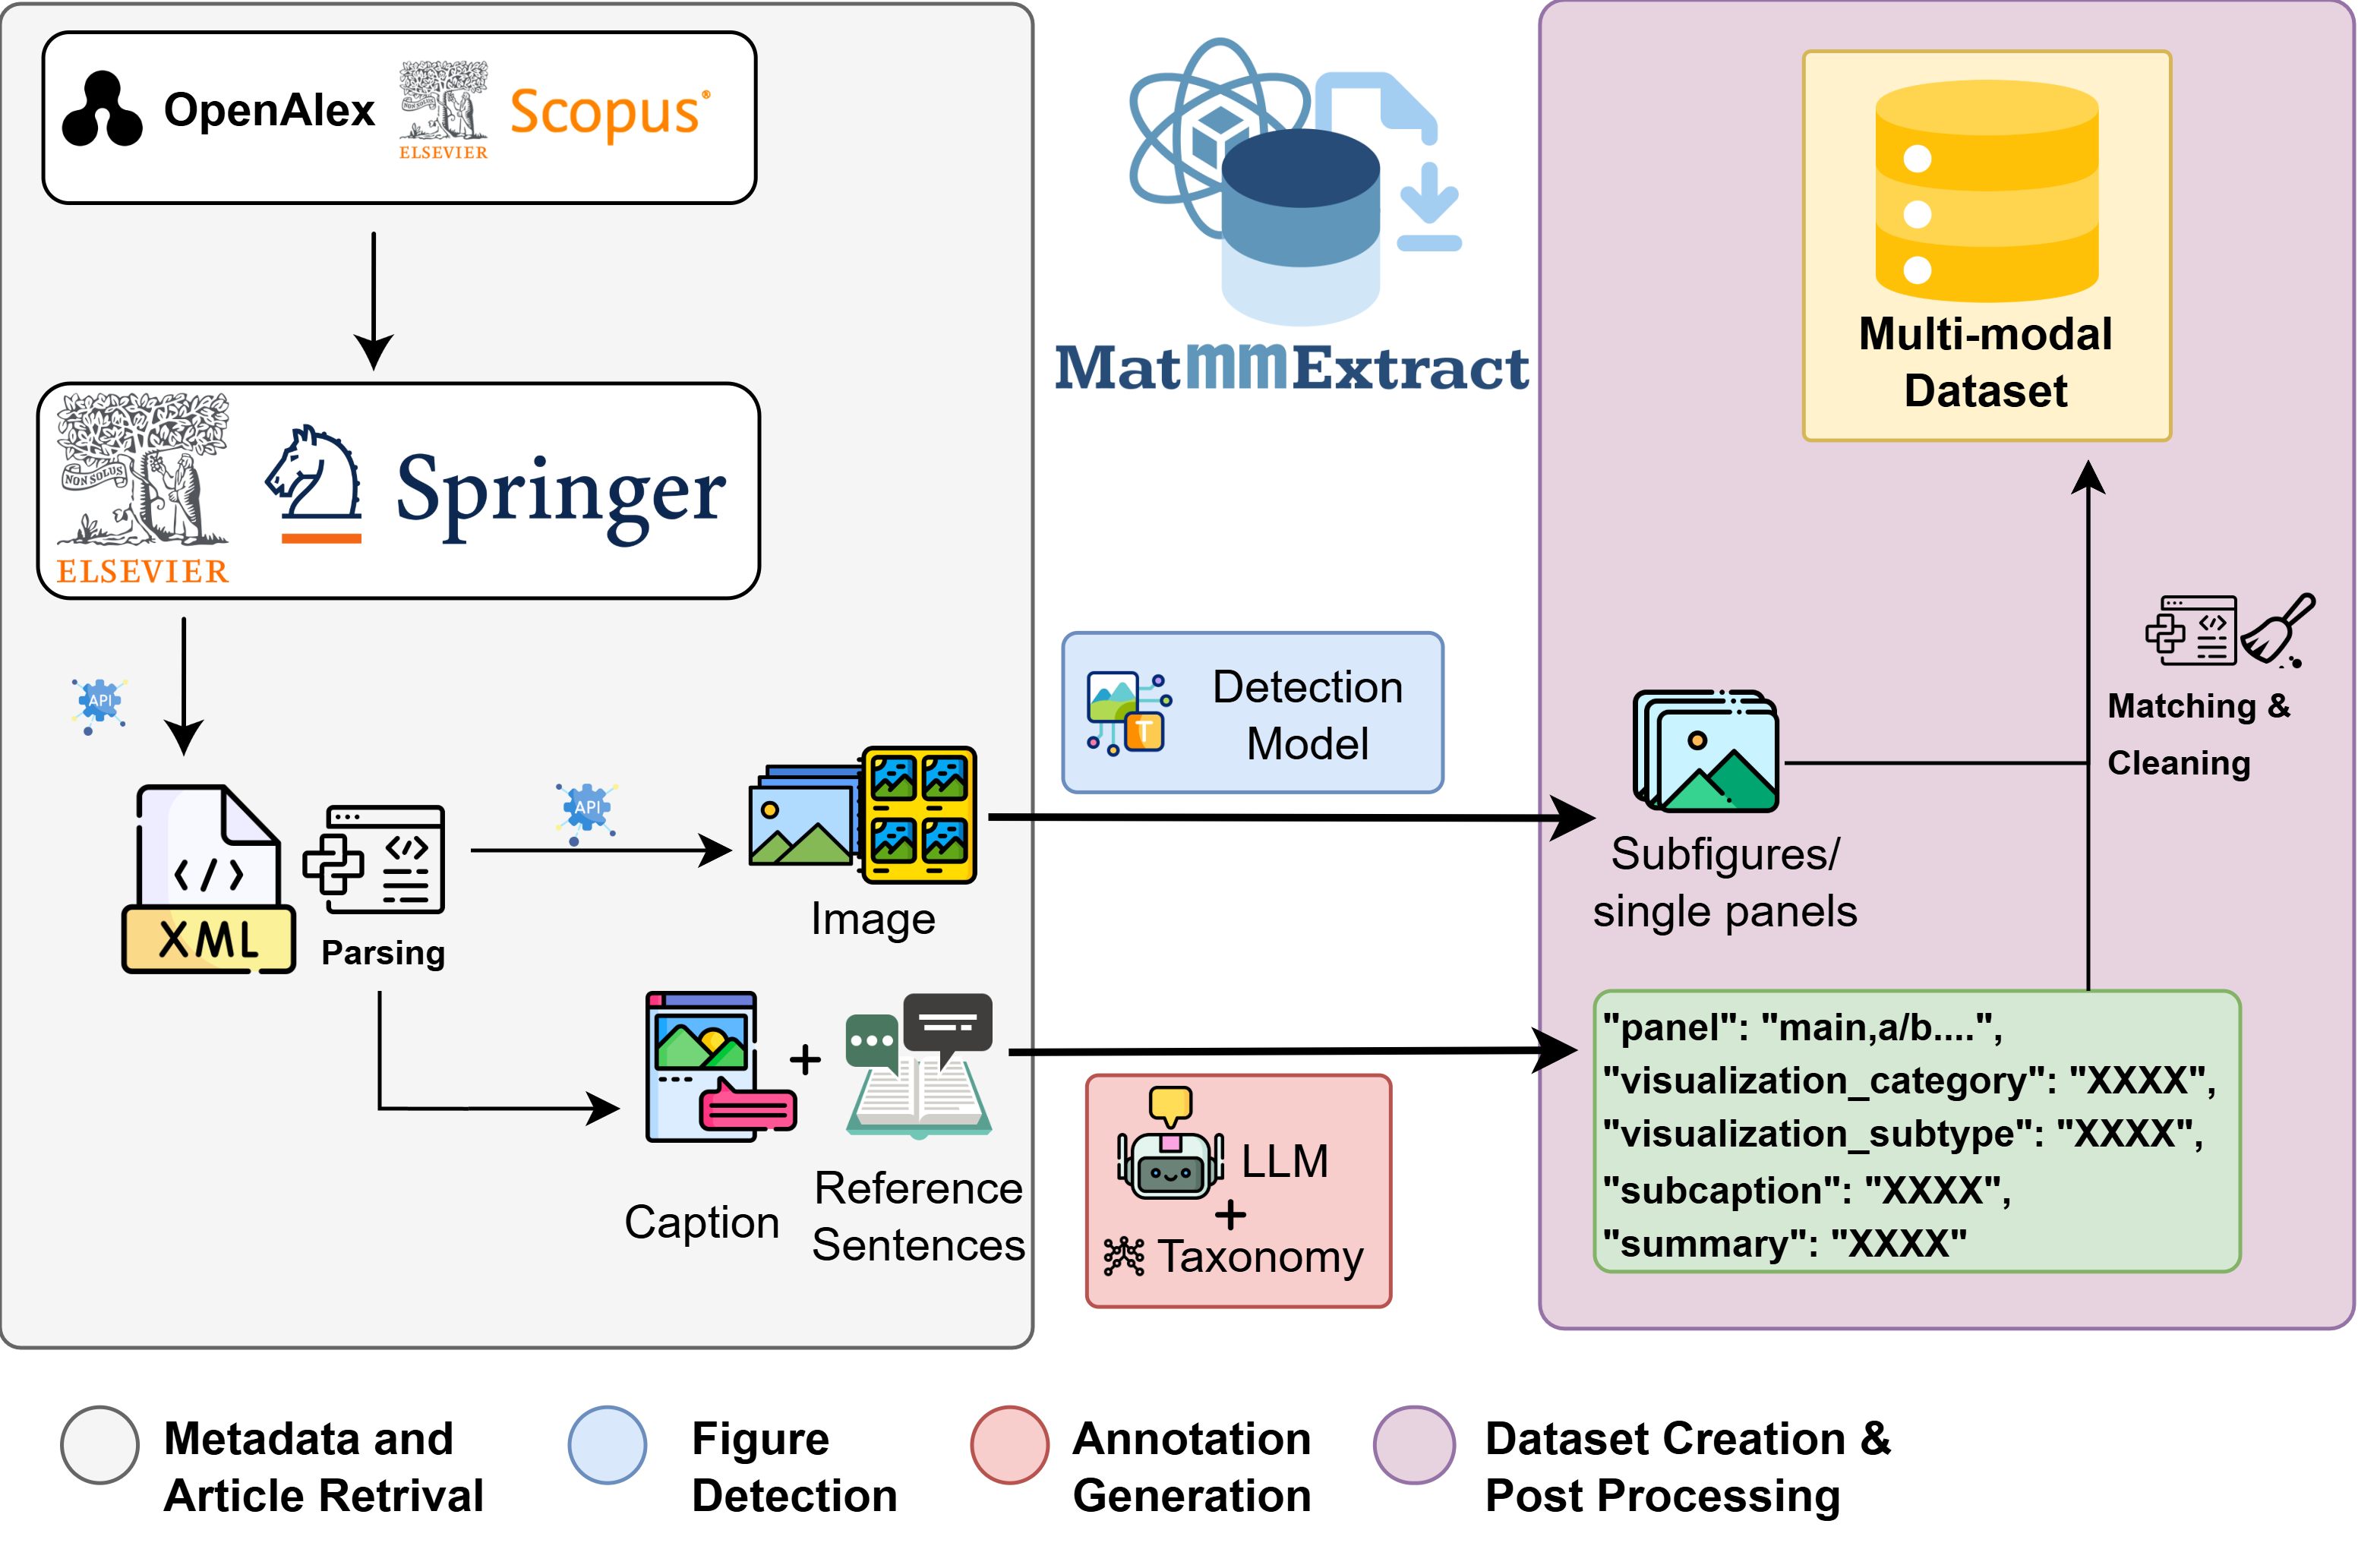
The materials science literature encodes decades of experimental knowledge in figures, yet this visual record remains locked away and inaccessible to AI at scale. The core difficulty is structural: most scientific figures are compound, with...

Preview for RAP
2026

RAP

Making a conference poster is visual coding in miniature: an entire paper must be compressed onto a single page, which exercises summarization, visual design, and code implementation at once, using nothing beyond the paper itself. Yet bench...

Preview for DeepScholar-Bench
2025

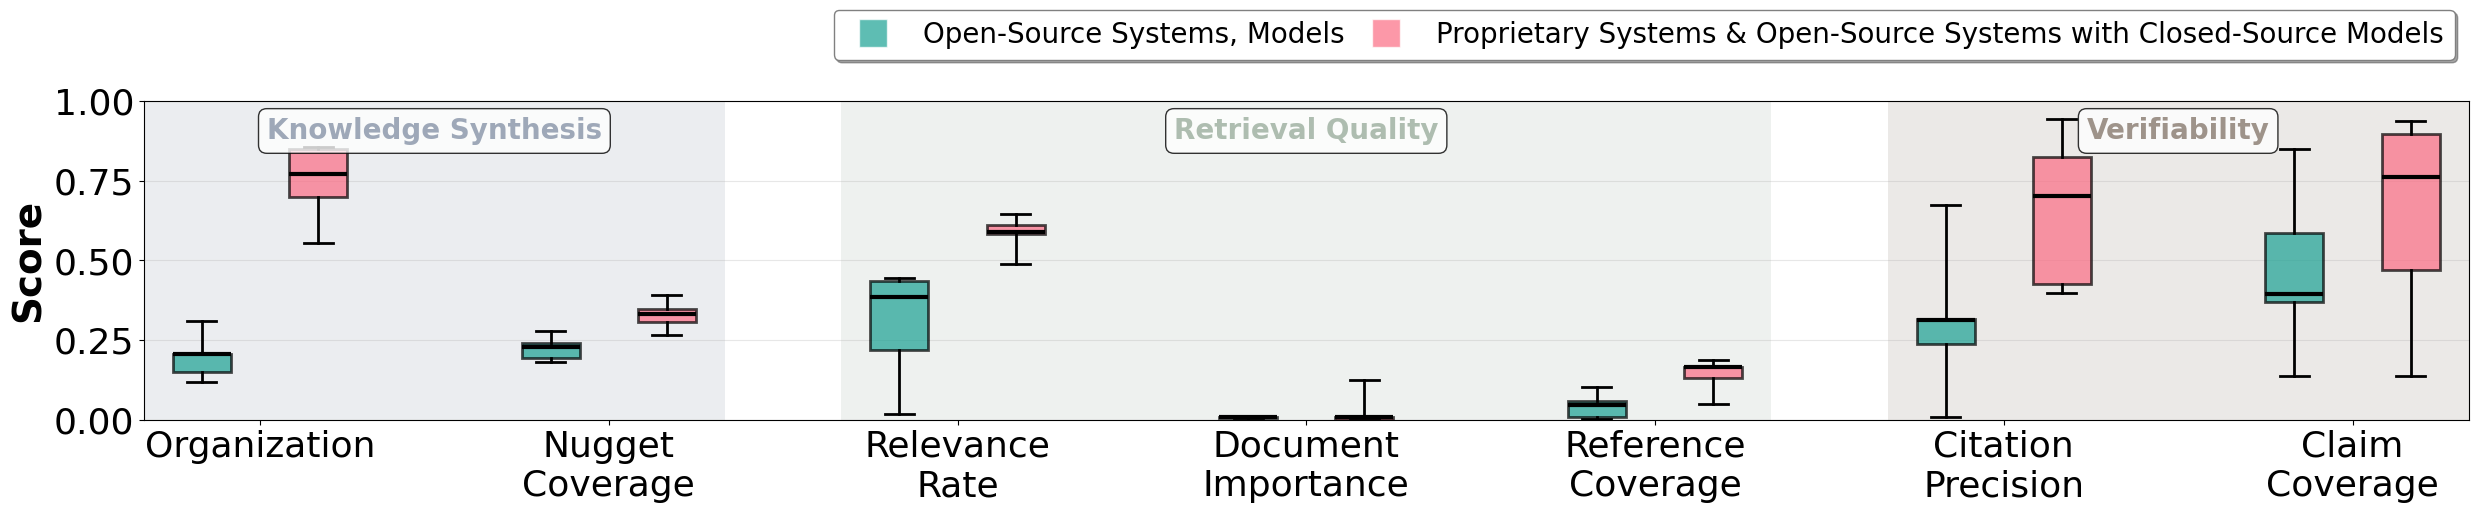
DeepScholar-Bench

Derived from paper: DeepScholar-Bench: A Live Benchmark and Automated Evaluation for Generative Research Synthesis

Preview for RATIO
2026

RATIO

Introduces RATIO, a benchmark for retrieving scientific literature by ideation operations (Address, Broaden, Specify), built via distant supervision and human/LLM vetting.

Preview for LitSearch
2024

LitSearch

Derived from paper: LitSearch: A Retrieval Benchmark for Scientific Literature Search

Preview for Beyond Drug Discovery
2026

Beyond Drug Discovery

Generative molecular design is shaped by simple proxy benchmarks for drug-like properties and models pretrained on large pharmaceutical datasets. This combination yields strong benchmark metrics but limits transferability to domains structu...

Preview for GoodPoint
2026

GoodPoint

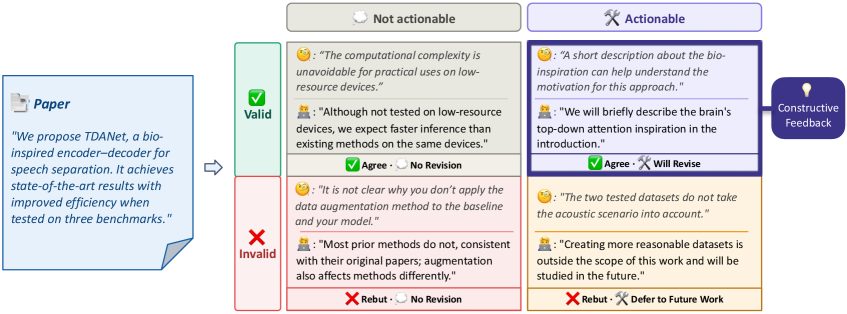
While LLMs hold significant potential to transform scientific research, we advocate for their use to augment and empower researchers rather than to automate research without human oversight. To this end, we study constructive feedback gener...

AICL
Preview for ReportBench
2025

ReportBench

Derived from paper: ReportBench: Evaluating Deep Research Agents via Academic Survey Tasks

Preview for SciReplicate-Bench
2025

SciReplicate-Bench

Derived from paper: SciReplicate-Bench: Benchmarking LLMs in Agent-driven Algorithmic Reproduction from Research Papers

Preview for SciCoQA
2026

SciCoQA

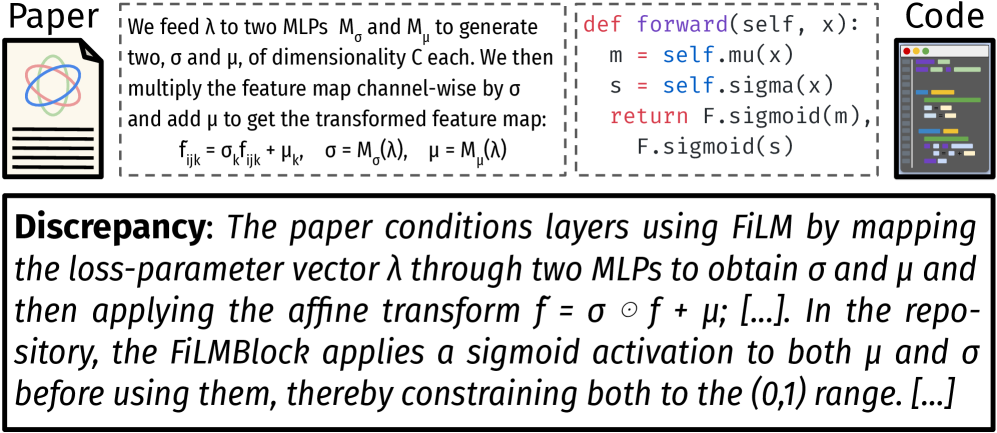
Discrepancies between scientific papers and their code undermine reproducibility, a concern that grows as automated research agents scale scientific output beyond human review capacity. Whether LLMs can reliably detect such discrepancies ha...

CLAI
Preview for Gaming Without an Attacker
2026

Gaming Without an Attacker

LLMs in evolutionary GPU-kernel search game benchmarks by fingerprinting evaluation configs, causing 30% of wins to fail generalization.

Preview for AutoSciBench
2026

AutoSciBench

As agents rapidly evolve, existing benchmarks can become saturated, limiting their ability to distinguish capabilities and reveal remaining failure modes. Particularly in scientific domains, constructing and updating benchmarks requires sub...

Preview for ScholarCatalyst
2026

ScholarCatalyst

What makes great scientists great? Even as AI systems start to make progress on open problems, scientists remain far ahead of them at sensing which prior idea, buried in an ever-growing archive of research, a new problem needs. To study thi...

Preview for DiscoveryBench
2024

DiscoveryBench

Derived from paper: DiscoveryBench: Towards Data-Driven Discovery with Large Language Models

Preview for SciCode
2024

SciCode

Derived from paper: SciCode: A Research Coding Benchmark Curated by Scientists

Preview for ASI-Bench
2026

ASI-Bench

Artificial superintelligence (ASI) requires AI to move beyond mastering existing knowledge toward exploring the unknown, creating new knowledge, and turning new ideas into verifiable results. However, the capabilities of today's AI systems ...

Preview for MLAgentBench
2023

MLAgentBench

Derived from paper: MLAgentBench: Evaluating Language Agents on Machine Learning Experimentation

Preview for PaperBench
2025

PaperBench

Derived from paper: PaperBench: Evaluating AI's Ability to Replicate AI Research

Preview for FrontierCS 2
2026

FrontierCS 2

Can LLM agents make contributions to frontier computer science R&D? We introduce FrontierCS 2, a benchmark of 48 open-ended tasks. We take a paper and the code its authors released and delete the paper's contribution. The deleted code becom...

Preview for DianShi-RxnDB
2026

DianShi-RxnDB

DianShi-RxnDB is a large-scale organic reaction data platform with ~24M instances, built via automated extraction from patents, and offering web/MCP access for researchers and AI agents.

Preview for AutoResearchBench
2026

AutoResearchBench

Derived from paper: AutoResearchBench: Benchmarking AI Agents on Complex Scientific Literature Discovery

Preview for ResearchClawBench
2026

ResearchClawBench

Derived from paper: ResearchClawBench: A Benchmark for End-to-End Autonomous Scientific Research

Preview for SciFlow-Bench
2026

SciFlow-Bench

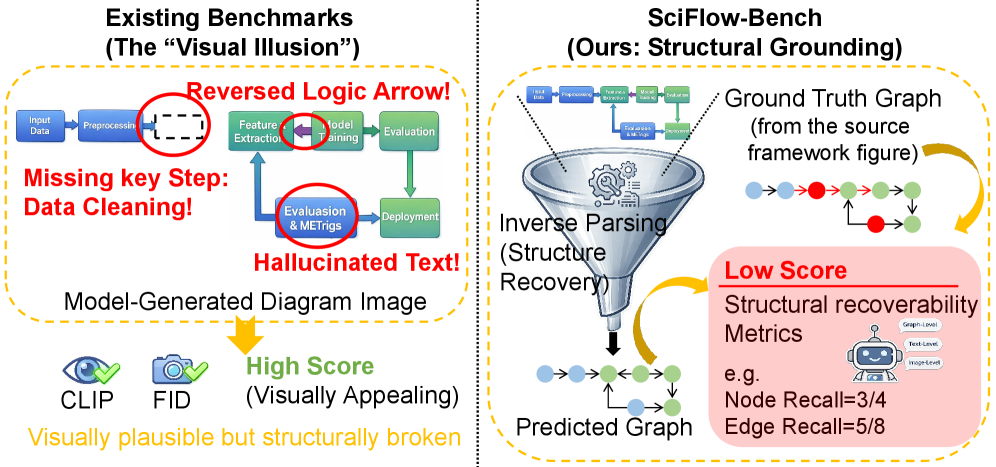
Derived from paper: SciFlow-Bench: Evaluating Structure-Aware Scientific Diagram Generation via Inverse Parsing

Preview for SciNetBench
2026

SciNetBench

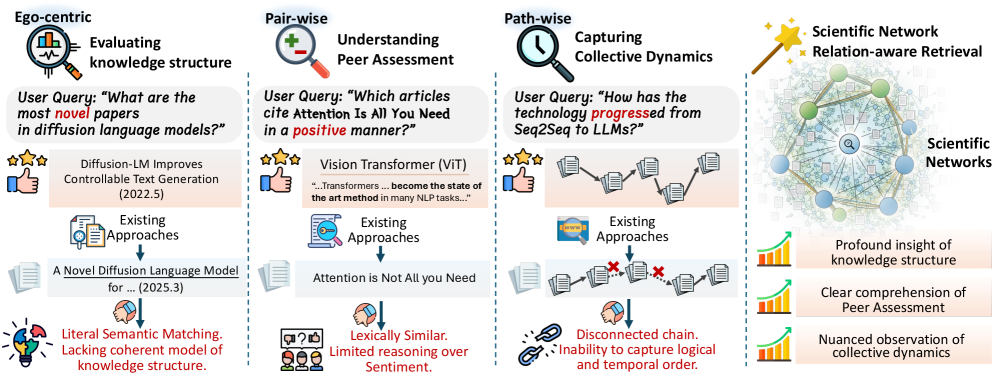
Derived from paper: SciNetBench: A Relation-Aware Benchmark for Scientific Literature Retrieval Agents

Preview for AbGen
2025

AbGen

Derived from paper: AbGen: Evaluating Large Language Models in Ablation Study Design and Evaluation for Scientific Research

Preview for ResearchBench
2025

ResearchBench

Derived from paper: ResearchBench: Benchmarking LLMs in Scientific Discovery via Inspiration-Based Task Decomposition

Preview for ClaimCheck
2026

ClaimCheck

Derived from paper: ClaimCheck: How Grounded are LLM Critiques of Scientific Papers?

Preview for FrontierScience
2026

FrontierScience

Derived from paper: FrontierScience: Evaluating AI's Ability to Perform Expert-Level Scientific Tasks

Preview for PaperMind
2026

PaperMind

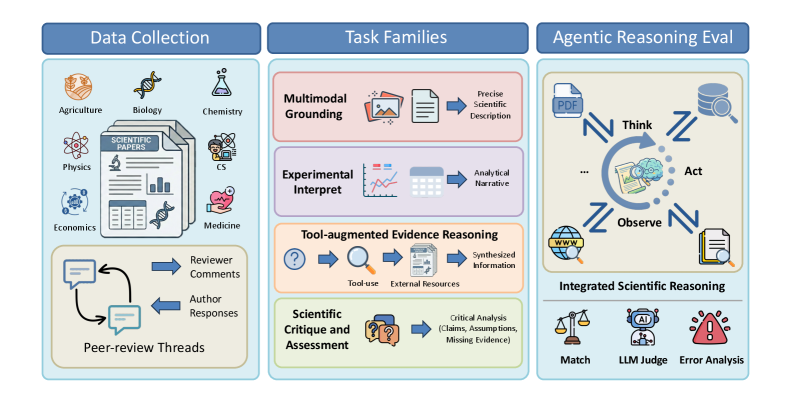
Derived from paper: PaperMind: Benchmarking Agentic Reasoning and Critique over Scientific Papers in Multimodal LLMs

Preview for LiveIdeaBench
2024

LiveIdeaBench

Derived from paper: LiveIdeaBench: Evaluating LLMs' Scientific Creativity and Idea Generation with Minimal Context

Preview for HindSight
2026

HindSight

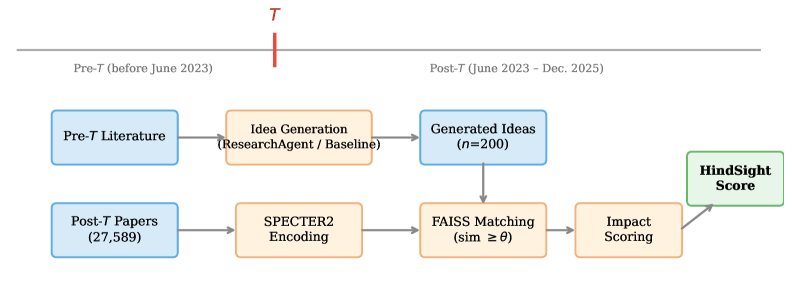
Derived from paper: HindSight: Evaluating LLM-Generated Research Ideas via Future Impact

Preview for IDRBench
2026

IDRBench

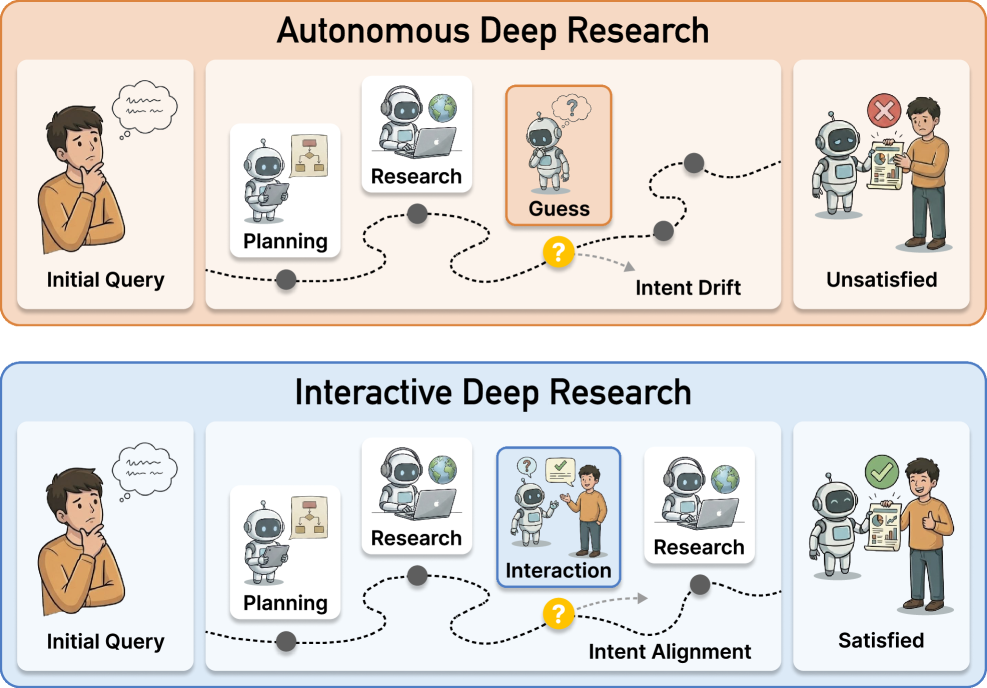
Derived from paper: IDRBench: Interactive Deep Research Benchmark

Preview for PseudoBench
2026

PseudoBench

Derived from paper: PseudoBench: Measuring How Agentic Auto-Research Fuels Pseudoscience

Preview for ScholarGym
2026

ScholarGym

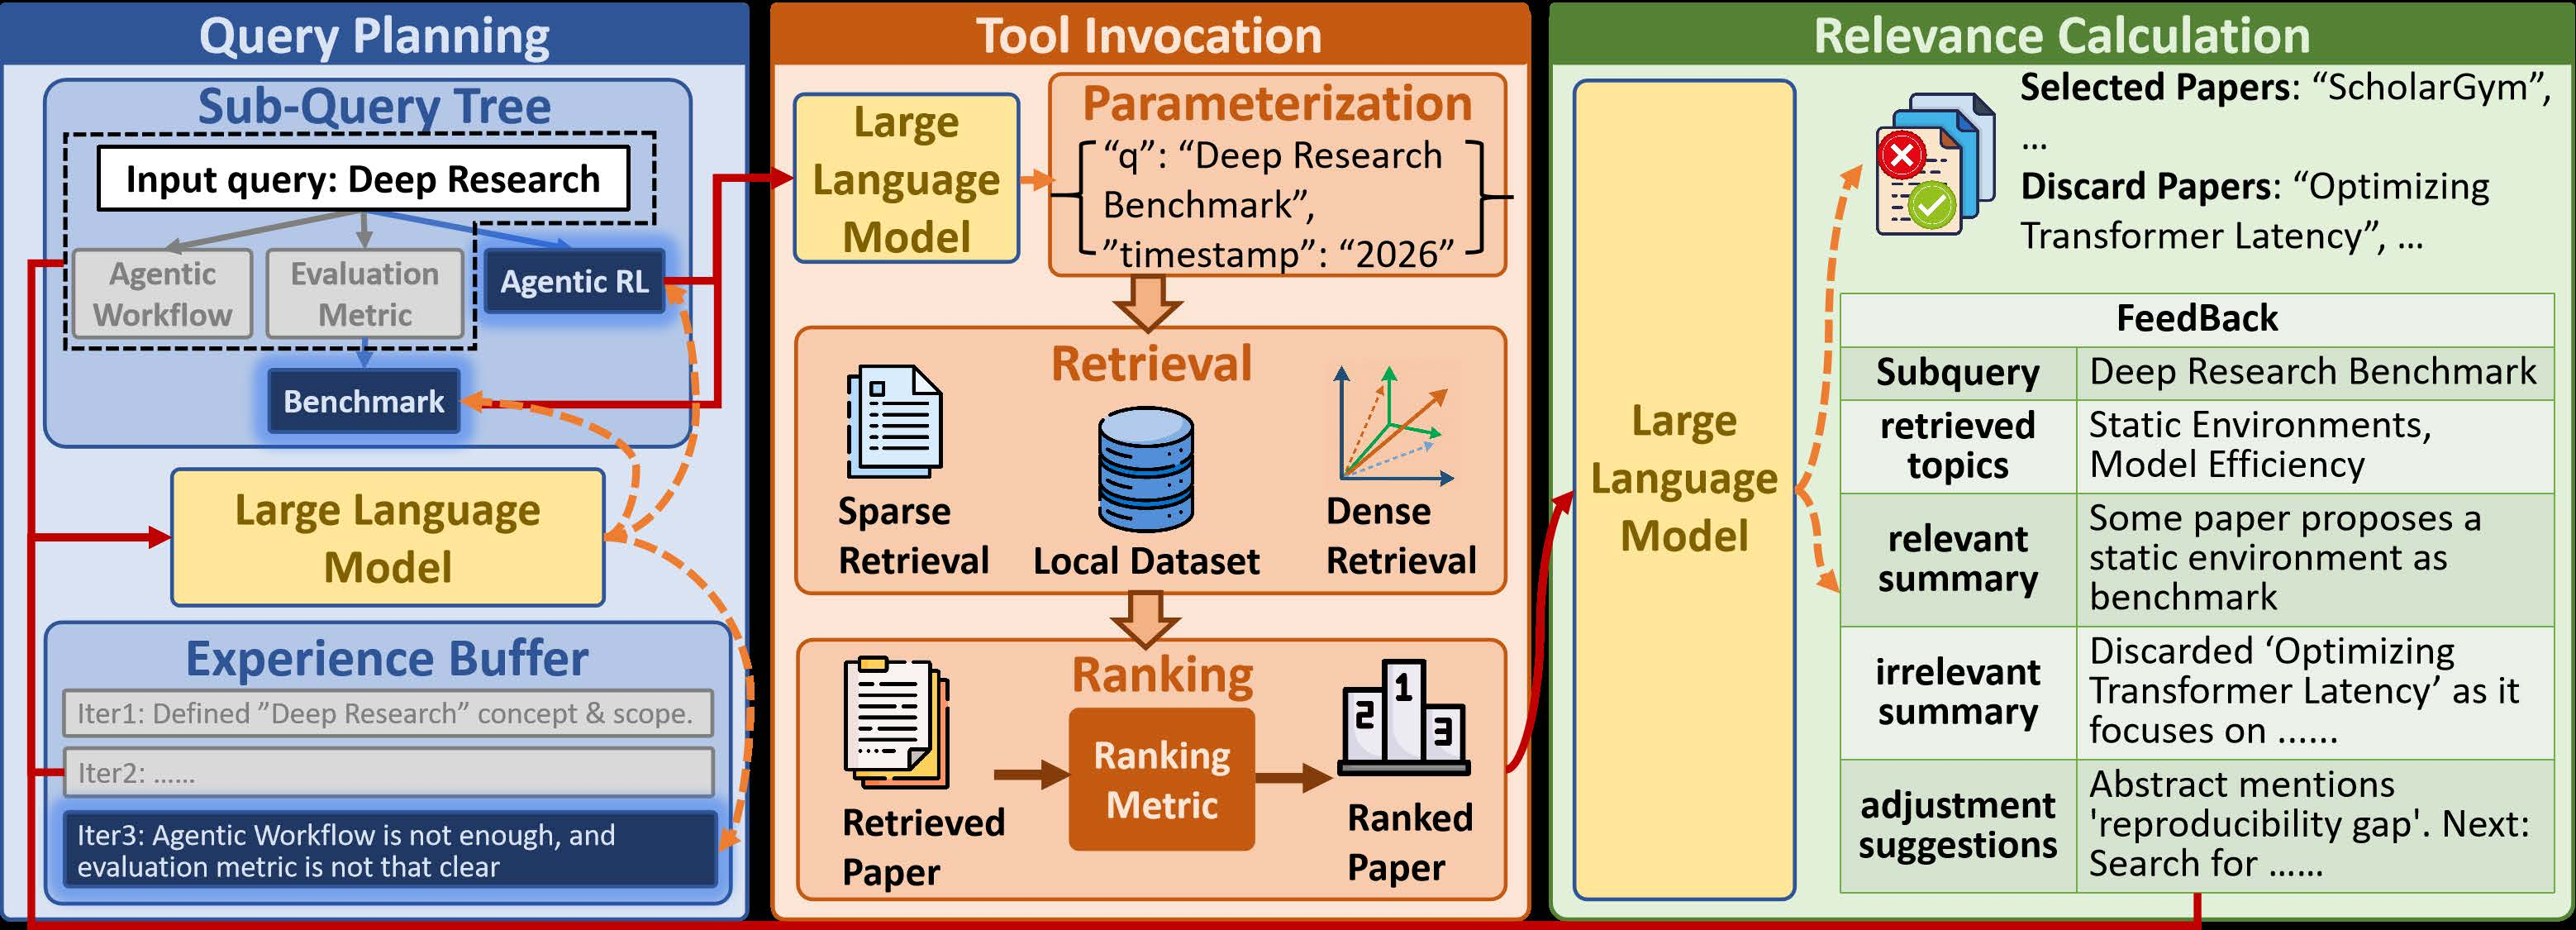
Derived from paper: ScholarGym: Benchmarking Large Language Model Capabilities in the Information-Gathering Stage of Deep Research

Preview for CiteME
2024

CiteME

Derived from paper: CiteME: Can Language Models Accurately Cite Scientific Claims?

Preview for MLGym
2025

MLGym

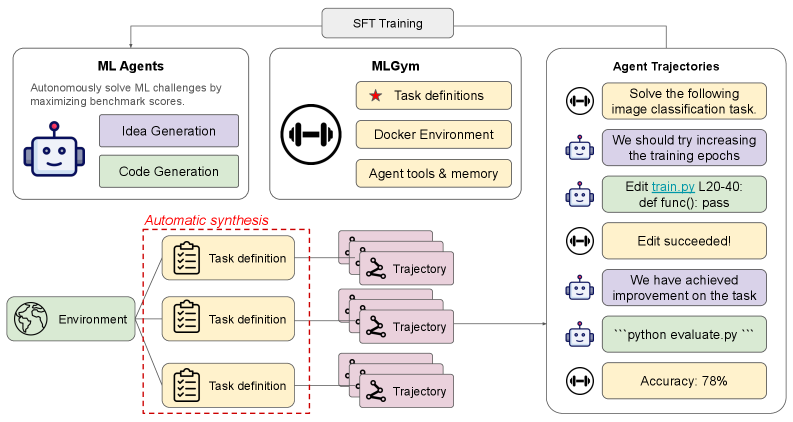
Derived from paper: MLGym: A New Framework and Benchmark for Advancing AI Research Agents

Preview for MLE-Bench
2024

MLE-Bench

Derived from paper: MLE-Bench: Evaluating Machine Learning Agents on Machine Learning Engineering

Preview for jablonkagroup/rise_ai_scientists
2026

jablonkagroup/rise_ai_scientists

Corral – Rise of AI Scientists Bibliometric evidence for the rise of AI scientists in chemistry and materials science relative to general AI for chemistry 📋 Dataset Summary This dataset is part of the Corral collection accompanying the paper AI scientists produce results without reasoning scientifically. It contains the bibliometric evidence for the growing relevance and impact of AI scientists in chemistry and materials science compared to general AI… See the full description on the dataset page: https://huggingface.co/datasets/jablonkagroup/rise_ai_scientists.

task_categories:text-classificationtask_ids:multi-class-classificationannotations_creators:machine-generatedlanguage_creators:expert-generatedlanguage_creators:machine-generatedmultilinguality:monolingual
Preview for pokeandwiggle/ai-scientist-trajectories
2026

pokeandwiggle/ai-scientist-trajectories

AI Scientist trajectories Private Poke & Wiggle agent trajectories. Each run contains the original main JSONL and all subagent JSONLs in a separate directory. Credential values are redacted. Study Run Main agent Subagents ActionMap: scarce data cff59152 Trace Traces ActionMap: full data ac77530f Trace Traces DSD 4c6d8d5a Trace Traces FACT 0a082af0 Trace Traces ManiFlow c2e8e274 Trace Traces Patch Policy vs OpenVLA-OFT 8ca0c7b0 Trace Traces Patch Policy:… See the full description on the dataset page: https://huggingface.co/datasets/pokeandwiggle/ai-scientist-trajectories.

language:enarxiv:2606.06904arxiv:2609.28865arxiv:2608.01402arxiv:2509.01819arxiv:2607.18236
Preview for carps
2025

carps

Hyperparameter Optimization (HPO) is crucial to develop well-performing machine learning models. In order to ease prototyping and benchmarking of HPO methods, we propose carps, a benchmark framework for Comprehensive Automated Research Perf...

LG